Predictive Maintenance MLOps Platform
Predicts industrial equipment failure from sensor data and serves it as a monitored, containerised API that CI retrains on every push.
About the data. This project uses the AI4I 2020 Predictive Maintenance dataset from the UCI Machine Learning Repository. It is a public benchmark dataset that its authors describe as synthetic, built to reflect real predictive maintenance data. The results show the method working on a benchmark, not on a real plant.
The problem
Unplanned downtime is expensive and mostly preventable. Most ML portfolio projects stop at a notebook with a good score, but in industry the hard part starts when the model has to keep working as the data shifts. I trained as a mechanical engineer, so I know downtime from the equipment side.
What I built
A cost-tuned model
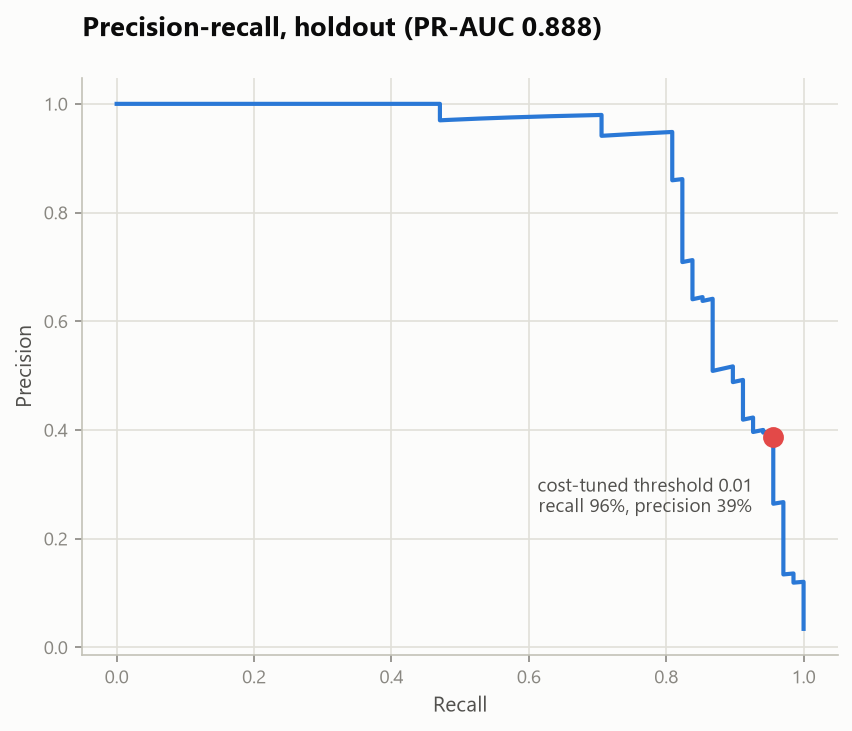
XGBoost against a logistic baseline it must beat. The alert threshold minimises expected cost: a missed failure (about £8,000) costs 27 times a false alarm (about £300), so it trades precision for 96% recall on purpose.
Explained predictions
A FastAPI service with strict Pydantic validation. Every prediction returns its top SHAP drivers, so an engineer sees why a machine was flagged.
Drift monitoring and CI
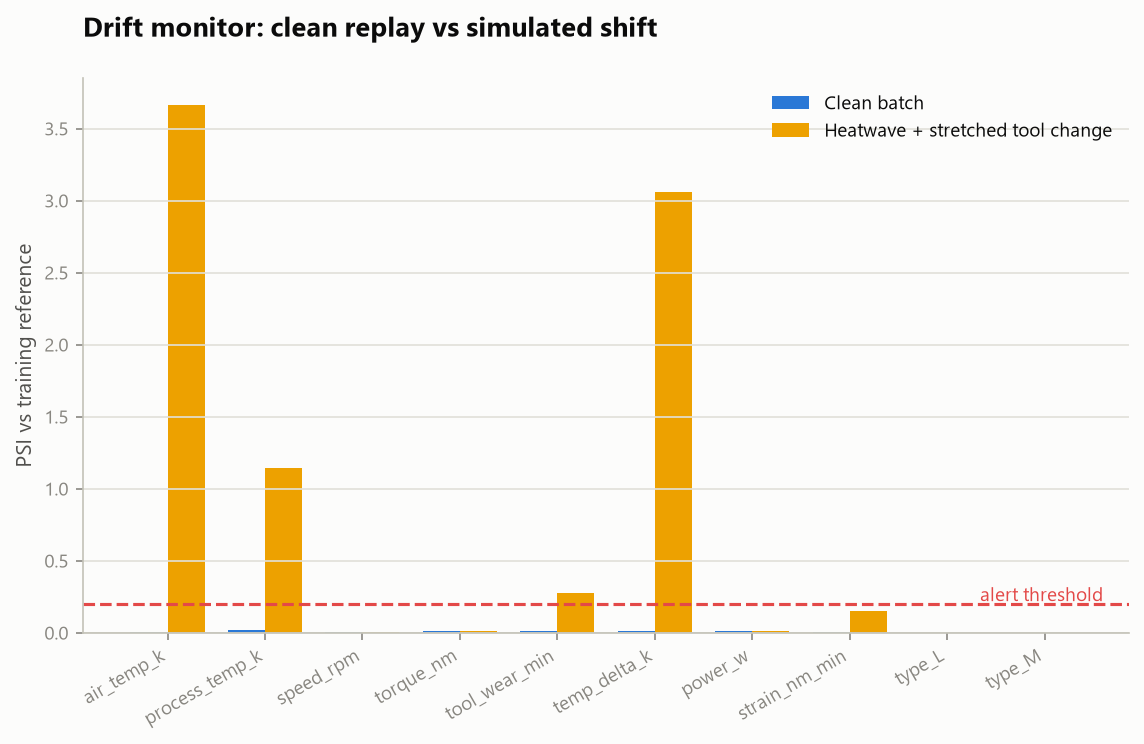
A Population Stability Index monitor written from scratch. CI retrains the model, runs the tests, builds the Docker image and smoke-tests a live prediction on every push.
How it works
- FeaturesOne shared feature function for training and serving, so skew cannot happen; leaky per-mode flags dropped at load
- TrainingBaseline against XGBoost with stratified CV, cost-tuned threshold, artifacts and drift reference saved
- Inference APIFastAPI /predict with SHAP drivers, /drift and /health, Dockerised with a healthcheck
- MonitoringPSI per feature against the training reference
- CI/CDGitHub Actions: retrain, test, docker build, live smoke test
What I found
- PR-AUC 0.888 and ROC-AUC 0.987 on a 2,000-cycle holdout. Cross-validated PR-AUC 0.855 against 0.459 for the logistic baseline.
- 96% recall at the cost-optimal threshold, with 39% precision by design. The cost model is documented in the repo.
- Clean replays stay under 0.03 PSI. A simulated heatwave with a stretched tool-change interval flags air temperature, cooling gap and tool wear, and nothing else.
- MLflow logging is optional, one environment variable, so the repo runs with zero infrastructure.
Limits and honest notes
- Trained on a public benchmark dataset, not on a real plant.
- 39% precision is a deliberate cost trade-off: the model raises more alarms so that it misses fewer failures.